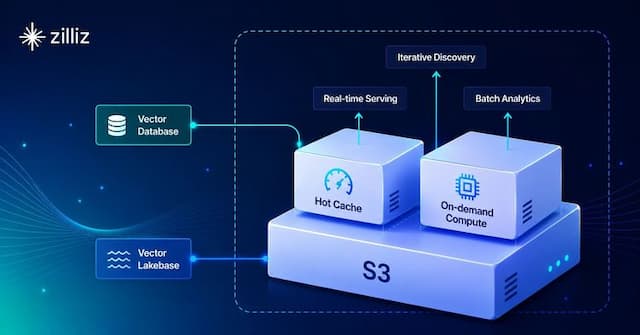
Vector search handles large datasets by leveraging efficient indexing techniques and scalable storage systems. Unlike traditional relational databases, which perform linear scans over records, vector search relies on indexes optimized for high-dimensional data. These indexes, such as Hierarchical Navigable Small World (HNSW), Locality-Sensitive Hashing (LSH), and Product Quantization (PQ), organize vectors in ways that allow fast similarity searches even as the dataset grows. For example, HNSW organizes vectors in a graph structure, where similar vectors are placed closer together, enabling faster nearest neighbor search. Additionally, vector databases like Milvus or Zilliz Cloud support horizontal scaling, meaning they can distribute data across multiple servers. This allows them to handle massive datasets with billions of vectors efficiently. As the dataset grows, these systems dynamically scale their infrastructure, ensuring high availability and low-latency searches. In some cases, these systems can even leverage specialized hardware like GPUs to accelerate vector search operations, improving performance when handling large datasets. Thus, the combination of optimized indexing, horizontal scaling, and hardware acceleration makes vector search highly effective for large datasets.
How does vector search handle large datasets?
Keep Reading
How do multi-speaker TTS systems function?
Multi-speaker text-to-speech (TTS) systems generate speech in different voices by incorporating speaker-specific informa
What are the limitations of time series analysis?
Time series analysis has several limitations that can affect its effectiveness and reliability. First, it assumes that t
How do you use JSON data in SQL?
Using JSON data in SQL provides a powerful way to store and manipulate semi-structured data within a relational database