How do you optimize embeddings for low-latency retrieval?
By zilliz
1 min read
To optimize embeddings for low-latency retrieval, several techniques can be employed to ensure fast query response times while maintaining the accuracy of results:
- Approximate Nearest Neighbor Search (ANN): Using algorithms like HNSW (Hierarchical Navigable Small World) graphs or Annoy, embeddings can be indexed in a way that allows for fast nearest-neighbor search without the need to search through the entire embedding space. These techniques significantly reduce latency by trading off some accuracy in favor of speed.
- Embedding Compression: Compressing the embeddings using techniques such as quantization or dimensionality reduction can reduce the time required to retrieve relevant results. Smaller embeddings can be processed more quickly during inference.
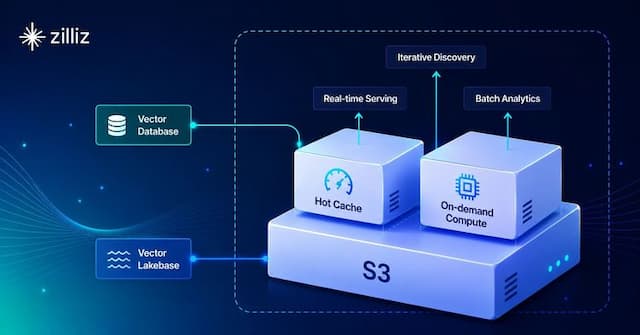
- Efficient Storage and Retrieval Structures: Storing embeddings in efficient data structures like vector databases (e.g., FAISS, Milvus) optimized for high-speed retrieval can greatly reduce latency.
By implementing these optimizations, you can significantly improve the speed of retrieval tasks while maintaining satisfactory accuracy.