Build RAG Chatbot with LangChain, Zilliz Cloud, Azure GPT-4o mini, and Cohere embed-english-v3.0
Introduction to RAG
Retrieval-Augmented Generation (RAG) is a game-changer for GenAI applications, especially in conversational AI. It combines the power of pre-trained large language models (LLMs) like OpenAI’s GPT with external knowledge sources stored in vector databases such as Milvus and Zilliz Cloud, allowing for more accurate, contextually relevant, and up-to-date response generation. A RAG pipeline usually consists of four basic components: a vector database, an embedding model, an LLM, and a framework.
Key Components We'll Use for This RAG Chatbot
This tutorial shows you how to build a simple RAG chatbot in Python using the following components:
- LangChain: An open-source framework that helps you orchestrate the interaction between LLMs, vector stores, embedding models, etc, making it easier to integrate a RAG pipeline.
- Zilliz Cloud: a fully managed vector database-as-a-service platform built on top of the open-source Milvus, designed to handle high-performance vector data processing at scale. It enables organizations to efficiently store, search, and analyze large volumes of unstructured data, such as text, images, or audio, by leveraging advanced vector search technology. It offers a free tier supporting up to 1 million vectors.
- Azure GPT-4o Mini: A compact version of the powerful GPT-4 architecture, designed for efficient processing in resource-constrained environments. It delivers robust performance in natural language understanding and generation, making it suitable for chatbots, customer support, and content creation. Ideal for applications where speed and scalability are essential without compromising on quality.
- Cohere embed-english-v3.0: This model specializes in generating high-quality text embeddings for English language input. It is designed for tasks like semantic search, recommendation systems, and document similarity, providing robust performance due to its deep contextual understanding. Ideal for applications needing nuanced language comprehension and efficient information retrieval.
By the end of this tutorial, you’ll have a functional chatbot capable of answering questions based on a custom knowledge base.
Note: Since we may use proprietary models in our tutorials, make sure you have the required API key beforehand.
Step 1: Install and Set Up LangChain
%pip install --quiet --upgrade langchain-text-splitters langchain-community langgraph
Step 2: Install and Set Up Azure GPT-4o mini
pip install -qU "langchain[openai]"
import getpass
import os

if not os.environ.get("AZURE_OPENAI_API_KEY"):
  os.environ["AZURE_OPENAI_API_KEY"] = getpass.getpass("Enter API key for Azure: ")

from langchain_openai import AzureChatOpenAI

llm = AzureChatOpenAI(
    azure_endpoint=os.environ["AZURE_OPENAI_ENDPOINT"],
    azure_deployment=os.environ["AZURE_OPENAI_DEPLOYMENT_NAME"],
    openai_api_version=os.environ["AZURE_OPENAI_API_VERSION"],
)
Step 3: Install and Set Up Cohere embed-english-v3.0
pip install -qU langchain-cohere
import getpass
import os

if not os.environ.get("COHERE_API_KEY"):
  os.environ["COHERE_API_KEY"] = getpass.getpass("Enter API key for Cohere: ")

from langchain_cohere import CohereEmbeddings

embeddings = CohereEmbeddings(model="embed-english-v3.0")
Step 4: Install and Set Up Zilliz Cloud
pip install -qU langchain-milvus
from langchain_milvus import Zilliz

vector_store = Zilliz(
    embedding_function=embeddings,
    connection_args={
        "uri": ZILLIZ_CLOUD_URI,
        "token": ZILLIZ_CLOUD_TOKEN,
    },
)
Step 5: Build a RAG Chatbot
Now that you’ve set up all components, let’s start to build a simple chatbot. We’ll use the Milvus introduction doc as a private knowledge base. You can replace it with your own dataset to customize your RAG chatbot.
import bs4
from langchain import hub
from langchain_community.document_loaders import WebBaseLoader
from langchain_core.documents import Document
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langgraph.graph import START, StateGraph
from typing_extensions import List, TypedDict

# Load and chunk contents of the blog
loader = WebBaseLoader(
    web_paths=("https://milvus.io/docs/overview.md",),
    bs_kwargs=dict(
        parse_only=bs4.SoupStrainer(
            class_=("doc-style doc-post-content")
        )
    ),
)

docs = loader.load()

text_splitter = RecursiveCharacterTextSplitter(chunk_size=1000, chunk_overlap=200)
all_splits = text_splitter.split_documents(docs)

# Index chunks
_ = vector_store.add_documents(documents=all_splits)

# Define prompt for question-answering
prompt = hub.pull("rlm/rag-prompt")


# Define state for application
class State(TypedDict):
    question: str
    context: List[Document]
    answer: str


# Define application steps
def retrieve(state: State):
    retrieved_docs = vector_store.similarity_search(state["question"])
    return {"context": retrieved_docs}


def generate(state: State):
    docs_content = "\n\n".join(doc.page_content for doc in state["context"])
    messages = prompt.invoke({"question": state["question"], "context": docs_content})
    response = llm.invoke(messages)
    return {"answer": response.content}


# Compile application and test
graph_builder = StateGraph(State).add_sequence([retrieve, generate])
graph_builder.add_edge(START, "retrieve")
graph = graph_builder.compile()
Test the Chatbot
Yeah! You've built your own chatbot. Let's ask the chatbot a question.
response = graph.invoke({"question": "What data types does Milvus support?"})
print(response["answer"])
Example Output
Milvus supports various data types including sparse vectors, binary vectors, JSON, and arrays. Additionally, it handles common numerical and character types, making it versatile for different data modeling needs. This allows users to manage unstructured or multi-modal data efficiently.
Optimization Tips
As you build your RAG system, optimization is key to ensuring peak performance and efficiency. While setting up the components is an essential first step, fine-tuning each one will help you create a solution that works even better and scales seamlessly. In this section, we’ll share some practical tips for optimizing all these components, giving you the edge to build smarter, faster, and more responsive RAG applications.
LangChain optimization tips
To optimize LangChain, focus on minimizing redundant operations in your workflow by structuring your chains and agents efficiently. Use caching to avoid repeated computations, speeding up your system, and experiment with modular design to ensure that components like models or databases can be easily swapped out. This will provide both flexibility and efficiency, allowing you to quickly scale your system without unnecessary delays or complications.
Zilliz Cloud optimization tips
Optimizing Zilliz Cloud for a RAG system involves efficient index selection, query tuning, and resource management. Use Hierarchical Navigable Small World (HNSW) indexing for high-speed, approximate nearest neighbor search while balancing recall and efficiency. Fine-tune ef_construction and M parameters based on your dataset size and query workload to optimize search accuracy and latency. Enable dynamic scaling to handle fluctuating workloads efficiently, ensuring smooth performance under varying query loads. Implement data partitioning to improve retrieval speed by grouping related data, reducing unnecessary comparisons. Regularly update and optimize embeddings to keep results relevant, particularly when dealing with evolving datasets. Use hybrid search techniques, such as combining vector and keyword search, to improve response quality. Monitor system metrics in Zilliz Cloud’s dashboard and adjust configurations accordingly to maintain low-latency, high-throughput performance.
Azure GPT-4o mini optimization tips
Azure GPT-4o mini is a cost-efficient, low-latency model optimized for fast RAG applications. Improve retrieval by ensuring only the top-ranked, most relevant documents are included in the context to minimize unnecessary token consumption. Structure prompts with bullet points or numbered lists for clarity. Adjust temperature settings between 0.1 and 0.2 for precision, modifying top-p as needed for response diversity. To enhance performance, batch multiple API requests and implement caching for frequently queried information. Azure’s infrastructure allows for auto-scaling, so configure dynamic scaling to handle varying workloads efficiently. Stream responses for improved real-time performance, ensuring fast and interactive user experiences. If used in a pipeline, assign GPT-4o mini to preliminary filtering or summarization while reserving larger models for complex tasks.
Cohere embed-english-v3.0 optimization tips
Cohere embed-english-v3.0 is a robust embedding model tailored for English language text. To optimize retrieval, preprocess input text to eliminate irrelevant noise and focus on key terms or phrases that will drive relevant matches. Use approximate nearest neighbor (ANN) algorithms like HNSW for efficient retrieval in large-scale datasets. For resource management, employ dimensionality reduction or quantization techniques to compress embeddings, reducing storage requirements without sacrificing too much performance. Implement multi-threading for batch processing to accelerate embedding generation. Use caching to store frequently accessed embeddings and reduce redundant computations. Fine-tune the model on specific data to improve performance on domain-specific queries and ensure greater relevance in retrieval.
By implementing these tips across your components, you'll be able to enhance the performance and functionality of your RAG system, ensuring it’s optimized for both speed and accuracy. Keep testing, iterating, and refining your setup to stay ahead in the ever-evolving world of AI development.
RAG Cost Calculator: A Free Tool to Calculate Your Cost in Seconds
Estimating the cost of a Retrieval-Augmented Generation (RAG) pipeline involves analyzing expenses across vector storage, compute resources, and API usage. Key cost drivers include vector database queries, embedding generation, and LLM inference.
RAG Cost Calculator is a free tool that quickly estimates the cost of building a RAG pipeline, including chunking, embedding, vector storage/search, and LLM generation. It also helps you identify cost-saving opportunities and achieve up to 10x cost reduction on vector databases with the serverless option.
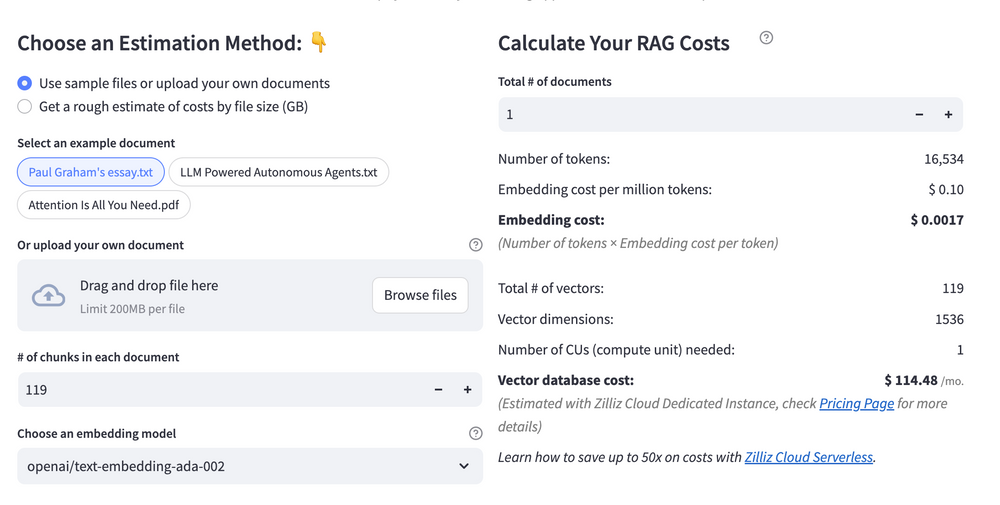 Calculate your RAG cost
What Have You Learned?
Wow, what an incredible journey we’ve been on together! Through this tutorial, you've learned how to harness the power of cutting-edge technologies to build a remarkable Retrieval-Augmented Generation (RAG) system. By integrating a robust framework like LangChain, we’ve seen how it seamlessly orchestrates the interaction between our various components, making it the backbone of your application. It’s like having a conductor lead an orchestra, ensuring everything plays perfectly together!
The vector database, powered by Zilliz Cloud, has shown us how it enables rapid searching and retrieval of information, allowing you to access data almost instantaneously. Imagine the possibilities when your applications can chat with users intelligently and efficiently!
Then there’s the LLM, utilizing Azure's GPT-4o mini. This powerhouse fuels conversational intelligence, letting your chatbot or application engage with users in a way that feels truly human. And let’s not forget the embedding model from Cohere, which enriches your interactions by converting words into meaningful representations—capturing the nuances of language and context.
With optimization tips in your toolkit and the free cost calculator at your disposal, you’re fully equipped to refine your RAG applications further. So what are you waiting for? Dive in, start building, and let your creativity soar. The world needs your innovative applications—go out there and make a difference with your newfound skills!
Further Resources
🌟 In addition to this RAG tutorial, unleash your full potential with these incredible resources to level up your RAG skills.
- How to Build a Multimodal RAG | Documentation
- How to Enhance the Performance of Your RAG Pipeline
- Graph RAG with Milvus | Documentation
- How to Evaluate RAG Applications - Zilliz Learn
- Generative AI Resource Hub | Zilliz
We'd Love to Hear What You Think!
We’d love to hear your thoughts! 🌟 Leave your questions or comments below or join our vibrant Milvus Discord community to share your experiences, ask questions, or connect with thousands of AI enthusiasts. Your journey matters to us!
If you like this tutorial, show your support by giving our Milvus GitHub repo a star ⭐—it means the world to us and inspires us to keep creating! 💖
Content
- Introduction to RAG
- Key Components We'll Use for This RAG Chatbot
- Step 1: Install and Set Up LangChain
- Step 2: Install and Set Up Azure GPT-4o mini
- Step 3: Install and Set Up Cohere embed-english-v3.0
- Step 4: Install and Set Up Zilliz Cloud
- Step 5: Build a RAG Chatbot
- Optimization Tips
- RAG Cost Calculator: A Free Tool to Calculate Your Cost in Seconds
- What Have You Learned?
- Further Resources
- We'd Love to Hear What You Think!
Vector Database at Scale
Zilliz Cloud is a fully-managed vector database built for scale, perfect for your RAG apps.
Try Zilliz Cloud for Free