How do you add vector search to Apache Iceberg tables?
Direct answer. You add vector search to an Apache Iceberg table by pointing a lake-native vector engine at the table's location, registering an embedding column over the existing data files (typically Parquet), and building an approximate-nearest-neighbor index in place. The index references the Iceberg snapshot's files on object storage and is refreshed incrementally as the table evolves — no export pipeline into a separate vector database (Pinecone, Weaviate, or similar), no duplicate storage. Iceberg's manifests, schema, and time-travel semantics stay the source of truth, while the engine handles the index and the low-latency query path.
How it works
If the embeddings don't yet exist as a column, the first step is to create them: batch-embed the source column (raw text, image paths, and so on) with your embedding model of choice and write the vectors back to the same Iceberg table as a new column. Once the embedding column exists — whether you just added it or it was already there — the indexing flow below is the same.
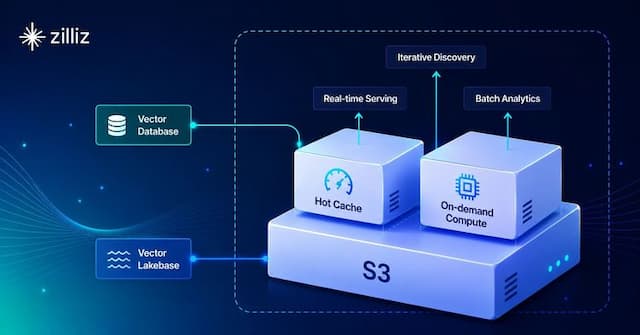
Apache Iceberg organizes data files (typically Parquet) into snapshots described by manifests, with a metadata layer for schema, partitioning, and history. A lake-native vector engine plugs into that structure rather than around it: it reads the embedding column from the snapshot's data files, builds an approximate-nearest-neighbor (ANN) index — typically an HNSW or IVF variant — and stores the index next to the data files. Queries hit the ANN index instead of scanning the whole table; when Iceberg writes a new snapshot, the engine refreshes incrementally and reprocesses only the files that changed.
The split of responsibilities:
| Layer | Iceberg's job | Engine's job |
|---|---|---|
| Storage | Parquet data files + manifests + snapshot list | The ANN index (HNSW / IVF / quantized variants) |
| Schema | Column types, evolution, partitioning | Embedding-column registration + similarity metric |
| Concurrency | Snapshot isolation, time travel | Index refresh tied to new snapshots |
| Consumers | Spark / Trino / Flink read the same files | Low-latency search API |
The canonical setup uses an external-collection pattern:
client.create_external_collection(
    collection_name="enterprise_docs",
    src="s3://my-warehouse/db/enterprise_docs/",   # Iceberg table location; exact form per the docs
    schema={"text": String, "embedding": FloatVector(768)},
)
client.create_index("enterprise_docs", field="embedding", index_type="HNSW")
results = client.search(
    collection_name="enterprise_docs",
    data=[query_embedding],
    top_k=10,
    output_fields=["text"],
)
The exact src form for an Iceberg table location is in the External Collections docs.
In practice (example)
In Zilliz Vector Lakebase, this end-to-end flow is the External Data Lake Search capability, surfaced through External Collections. You point the API at the Iceberg path, build the index, and serve — the embeddings stay in your Iceberg warehouse, governed by your existing catalog. Vector Lakebase builds on the Milvus serving engine, so the same Milvus index types and tunables apply to the query path.
Our architecture write-up illustrates the mode-by-mode latency profile for a 1B-vector Iceberg setup — illustrative figures from that engineering account, not a formally specified benchmark:
| Mode | Latency | Context |
|---|---|---|
| Spark brute-force scan (no index) | hours | what the lake gives you without an index |
| Cold — just-built index | ~30 seconds | index builds from the Iceberg table in ~20 minutes |
| Warm — disk cache | double-digit milliseconds | index cached on local SSD |
| Hot — in-memory | single-digit milliseconds | production serving |
The contrast with the brute-force scan is why pure batch jobs over an Iceberg table don't substitute for a serving layer — the index, not the table, is what makes interactive queries possible.
Related questions
- Can you search a data lake without moving data? — the high-level answer
- What is zero-copy search in vector databases? — the underlying concept
- What is Apache Iceberg? — table-format primer
- Vector search on your data lake, end to end — the deep-dive guide
- Vector Lakebase — product overview
In short. You don't need a separate vector database to make an Apache Iceberg table searchable by similarity. Build the ANN index over the snapshot's files in place, refresh incrementally as snapshots change, and let Iceberg remain the source of truth. See the Vector Lakebase launch overview for the broader architecture.