Can you search a data lake without moving data?
Direct answer. Yes. You can run vector search directly over data that already sits in your data lake — Parquet, Iceberg, or Lance files on S3 or another object store — by building a vector index over those files in place. The index references the existing data, queries hit the index, the source files stay put, and only changed files are reprocessed on refresh. That removes the ETL job, the sync pipeline, and the duplicate storage a separate vector database would otherwise require. The trade-off is cold-start latency on the first query, which lake-native engines reduce with caching, partial loading, and quantization.
How searching in place works
The pattern has two parts: register the files, then build an index over them.
The standard alternative is an export pipeline — Spark for batch embedding, Kafka for change capture, a separate vector store such as Pinecone, Weaviate, or Qdrant for serving. Every update has to flow through that pipeline, and your data lives in two places. In-place search skips the pipeline: the engine reads the embedding column directly from your Parquet, Iceberg, or Delta Lake files on object storage and builds an approximate-nearest-neighbor (ANN) index that points at those files. Queries run against the index; the source data stays where it is. When a file changes, an incremental refresh reprocesses only that file rather than re-embedding the whole dataset.
lake table (Iceberg / Parquet on S3)
      │  register + index in place (no copy)
      ▼
vector index  ──►  query ──► results
      ▲  incremental refresh on changed files only
The reason this was historically slow is physics, not design. Object stores answer reads in tens of milliseconds — orders of magnitude slower than RAM — and a naive HNSW (Hierarchical Navigable Small World) graph traversal touches hundreds of nodes per query, so each lookup fans out into many sequential S3 reads. A one-billion-vector HNSW index can reach hundreds of gigabytes; pulling it cold from object storage takes minutes. Lake-native engines close that gap with two tools. The first is clustering and pruning, so a query scans only a small fraction of the data — around three percent in published setups. The second is quantization: a RaBitQ-style 1+3-bit two-stage scheme can compress a roughly 340 GB index to about 13 GB at the 1-bit coarse stage (with 85–90% recall) and then rerank with the extra 3 bits to about 95% recall.
In practice (example)
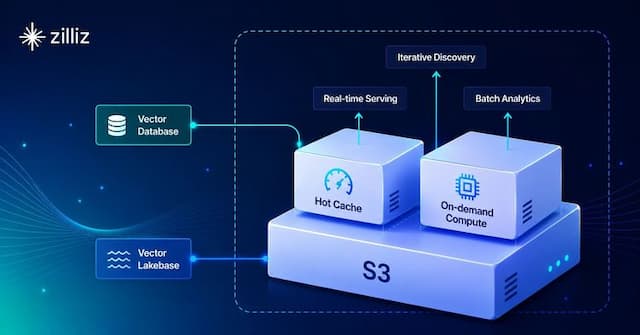
For example, in Zilliz Vector Lakebase this is the External Data Lake Search capability, surfaced through External Collections. You call create_external_collection against an S3 bucket or Iceberg path, call create_index to build the ANN index in place (the index persists back to S3 alongside the source files), and then search. The data itself never moves, and a refresh only reprocesses files that changed. Vector Lakebase builds on the Milvus serving engine, so the query path inherits Milvus's index types and tunables.
Our architecture write-up illustrates the mode-by-mode latency profile for a one-billion-vector Iceberg setup — illustrative figures from that engineering account, not a formally specified benchmark:
| Mode | Latency | Context |
|---|---|---|
| Spark brute-force scan (no index) | hours | baseline lake scan over the same data |
| Cold — just-built index | ~30 seconds | index builds from the Iceberg table in ~20 minutes |
| Warm — disk cache | double-digit milliseconds | index cached on local SSD |
| Hot — in-memory | single-digit milliseconds | production serving |
The Spark-scan baseline is the reason pure lake-side scans don't substitute for an indexed serving path.
Related questions
- How do you add vector search to Apache Iceberg tables? — the step-by-step version
- What is zero-copy search in vector databases? — the underlying concept
- Vector search on your data lake, end to end — the deep-dive guide
- Vector Lakebase — product overview
In short. You don't have to copy your data lake into a vector database to search it: index the embeddings in place over your existing Parquet or Iceberg files and query that index, so the source data stays where it lives. See the Vector Lakebase launch overview for the broader architecture.