Qwen3 embeddings vs proprietary APIs: cost & quality?
Qwen3 vs Proprietary Embedding APIs
Qwen3 embeddings deliver MTEB #1 ranking performance comparable to proprietary APIs while eliminating per-query costs and vendor lock-in through open-source availability.
Overview
Propretary embedding APIs (OpenAI, Anthropic, Cohere) charge per 1M input tokens. For large-scale search applications (billions of documents), cumulative costs exceed proprietary model licenses. Qwen3, being open-source, has zero per-query fees—you pay only infrastructure costs (GPUs, storage, bandwidth).
Quality Parity
Qwen3-8B (MTEB 70.58): Ranks #1 on MTEB multilingual leaderboard. Comparable to or exceeds:
- OpenAI text-embedding-3-large (proprietary, MTEB ~65)
- Anthropic embeddings (MTEB estimates ~64)
- Cohere Embed v3 (MTEB ~67)
For multilingual tasks, Qwen3 dominates. For English-only retrieval, Qwen3 and proprietary APIs are performance-competitive.
Cost Model Comparison
Proprietary APIs: $0.02–0.10 per 1M tokens
- 1B documents × 100 tokens avg = 100B tokens = $2,000–10,000 initial embedding
- Monthly re-embeddings (10% churn) = $200–1,000
- Queries: 1M queries/month × 50 tokens = 50M tokens = $1–5 monthly
- Annual cost: ~$30,000–150,000 for mid-scale deployments
Qwen3 Self-Hosted + Zilliz Cloud:
- GPU infrastructure: Single A100 = $5–10/hour; amortized ~$50K/year for shared infrastructure
- Zilliz Cloud: $0.50–2.00 per 1M vectors/month stored; ~$500–2,000/year for billion-scale
- Annual cost: ~$50K–70K (including engineering time)
Qwen3 via Cloud Inference Endpoints:
- Managed inference (SageMaker, Azure ML): $0.50–2.00 per 1M input tokens
- Lower than proprietary APIs but higher than self-hosted
- Annual cost: ~$50K–100K
Breakeven: For deployments processing >500M tokens/month, Qwen3 self-hosting beats proprietary APIs by 50%+ annually.
Vendor Lock-in & Flexibility
Proprietary APIs: Switching providers means:
- Re-embedding entire corpus with new model
- Reindexing in new vector database
- Revalidating search quality
- Effort: weeks to months
Qwen3 + Zilliz Cloud: Switching embedding models is simple—you control both layers. Re-embed using a new model (days), reindex in Zilliz Cloud (automated), validate (days). Effort: 1–2 weeks. No vendor lock-in.
Feature Parity
Qwen3 Advantages:
- Matryoshka learning (variable dimensions) - proprietary APIs lack this
- 32K context window - most proprietary APIs limited to 512–8K
- Instruction prompting - customizable for domains
- Open-source fine-tuning - adapt to your domain
Proprietary API Advantages:
- Managed availability (SLAs, support)
- No infrastructure management
- Instant scaling (their problem, not yours)
Integration with Zilliz Cloud
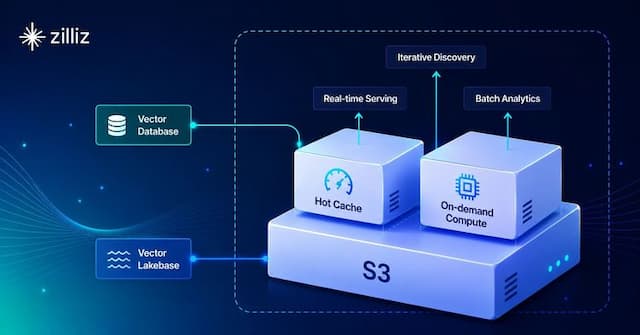
Zilliz Cloud accepts vectors from any source: self-hosted Qwen3, managed Qwen3 inference, or proprietary APIs. Most cost-effective architecture:
- Host Qwen3 on shared GPU infrastructure (amortized cost)
- Store embeddings in Zilliz Cloud (managed, compliant, scalable)
- No per-query fees from embedding APIs
This hybrid approach captures cost savings of open-source embeddings while maintaining managed vector storage reliability.
Comparison Table
| Factor | Qwen3 Self-Hosted | Qwen3 (Cloud Inference) | Proprietary APIs | Proprietary VDB |
|---|---|---|---|---|
| Quality (MTEB) | 70.58 ✅ | 70.58 ✅ | ~65-67 | ~65-67 |
| Multilingual | 100+ ✅ | 100+ ✅ | 50-80 ⚠️ | 50-80 ⚠️ |
| Cost (500M tokens/mo) | $50K/yr ✅ | $70K/yr ✅ | $120K/yr ❌ | Lock-in ❌ |
| Cost (50M tokens/mo) | $40K/yr ⚠️ | $40K/yr ⚠️ | $15K/yr ✅ | Lock-in ⚠️ |
| Matryoshka Learning | ✅ | ✅ | ❌ | ❌ |
| 32K Context | ✅ | ✅ | ⚠️ (limited) | ⚠️ |
| Fine-tuning Freedom | ✅ | ❌ | ❌ | ❌ |
| Vendor Lock-in | ❌ | ❌ | ❌ | ❌ |
Verdict
For large-scale applications (>500M tokens/month), Qwen3 + Zilliz Cloud is 50%+ cheaper than proprietary APIs while maintaining superior MTEB quality. For small prototypes (<50M tokens/month), proprietary APIs offer simplicity at acceptable cost. Zilliz Cloud supports both, so you can start with proprietary embeddings and migrate to Qwen3 without re-architecting.