Build RAG Chatbot with LangChain, Zilliz Cloud, Cohere Command R, and Nomic Embed Text V2
Introduction to RAG
Retrieval-Augmented Generation (RAG) is a game-changer for GenAI applications, especially in conversational AI. It combines the power of pre-trained large language models (LLMs) like OpenAI’s GPT with external knowledge sources stored in vector databases such as Milvus and Zilliz Cloud, allowing for more accurate, contextually relevant, and up-to-date response generation. A RAG pipeline usually consists of four basic components: a vector database, an embedding model, an LLM, and a framework.
Key Components We'll Use for This RAG Chatbot
This tutorial shows you how to build a simple RAG chatbot in Python using the following components:
- LangChain: An open-source framework that helps you orchestrate the interaction between LLMs, vector stores, embedding models, etc, making it easier to integrate a RAG pipeline.
- Zilliz Cloud: a fully managed vector database-as-a-service platform built on top of the open-source Milvus, designed to handle high-performance vector data processing at scale. It enables organizations to efficiently store, search, and analyze large volumes of unstructured data, such as text, images, or audio, by leveraging advanced vector search technology. It offers a free tier supporting up to 1 million vectors.
- Cohere Command R: This model is designed for high-performance retrieval tasks, offering advanced capabilities in understanding and generating natural language. Its strengths lie in semantic search and document summarization, making it ideal for applications such as customer support, content generation, and knowledge management, where accuracy and context relevance are paramount.
- Nomic Embed Text V2: An open-source, multilingual text embedding model using a Mixture-of-Experts (MoE) architecture for efficient processing. Trained on 1.6 billion text pairs, it excels in retrieval tasks, supports flexible embedding dimensions, and optimizes storage and compute costs. Its training data and code are fully open-sourced for transparency.
By the end of this tutorial, you’ll have a functional chatbot capable of answering questions based on a custom knowledge base.
Note: Since we may use proprietary models in our tutorials, make sure you have the required API key beforehand.
Step 1: Install and Set Up LangChain
%pip install --quiet --upgrade langchain-text-splitters langchain-community langgraph
Step 2: Install and Set Up Cohere Command R
pip install -qU "langchain[cohere]"
import getpass
import os

if not os.environ.get("COHERE_API_KEY"):
  os.environ["COHERE_API_KEY"] = getpass.getpass("Enter API key for Cohere: ")

from langchain.chat_models import init_chat_model

llm = init_chat_model("command-r", model_provider="cohere")
Step 3: Install and Set Up Nomic Embed Text V2
pip install -qU langchain-nomic
import getpass
import os

if not os.environ.get("NOMIC_API_KEY"):
  os.environ["NOMIC_API_KEY"] = getpass.getpass("Enter API key for Nomic: ")

from langchain_nomic import NomicEmbeddings

embeddings = NomicEmbeddings(model="nomic-ai/nomic-embed-text-v2-moe")
Step 4: Install and Set Up Zilliz Cloud
pip install -qU langchain-milvus
from langchain_milvus import Zilliz

vector_store = Zilliz(
    embedding_function=embeddings,
    connection_args={
        "uri": ZILLIZ_CLOUD_URI,
        "token": ZILLIZ_CLOUD_TOKEN,
    },
)
Step 5: Build a RAG Chatbot
Now that you’ve set up all components, let’s start to build a simple chatbot. We’ll use the Milvus introduction doc as a private knowledge base. You can replace it with your own dataset to customize your RAG chatbot.
import bs4
from langchain import hub
from langchain_community.document_loaders import WebBaseLoader
from langchain_core.documents import Document
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langgraph.graph import START, StateGraph
from typing_extensions import List, TypedDict

# Load and chunk contents of the blog
loader = WebBaseLoader(
    web_paths=("https://milvus.io/docs/overview.md",),
    bs_kwargs=dict(
        parse_only=bs4.SoupStrainer(
            class_=("doc-style doc-post-content")
        )
    ),
)

docs = loader.load()

text_splitter = RecursiveCharacterTextSplitter(chunk_size=1000, chunk_overlap=200)
all_splits = text_splitter.split_documents(docs)

# Index chunks
_ = vector_store.add_documents(documents=all_splits)

# Define prompt for question-answering
prompt = hub.pull("rlm/rag-prompt")


# Define state for application
class State(TypedDict):
    question: str
    context: List[Document]
    answer: str


# Define application steps
def retrieve(state: State):
    retrieved_docs = vector_store.similarity_search(state["question"])
    return {"context": retrieved_docs}


def generate(state: State):
    docs_content = "\n\n".join(doc.page_content for doc in state["context"])
    messages = prompt.invoke({"question": state["question"], "context": docs_content})
    response = llm.invoke(messages)
    return {"answer": response.content}


# Compile application and test
graph_builder = StateGraph(State).add_sequence([retrieve, generate])
graph_builder.add_edge(START, "retrieve")
graph = graph_builder.compile()
Test the Chatbot
Yeah! You've built your own chatbot. Let's ask the chatbot a question.
response = graph.invoke({"question": "What data types does Milvus support?"})
print(response["answer"])
Example Output
Milvus supports various data types including sparse vectors, binary vectors, JSON, and arrays. Additionally, it handles common numerical and character types, making it versatile for different data modeling needs. This allows users to manage unstructured or multi-modal data efficiently.
Optimization Tips
As you build your RAG system, optimization is key to ensuring peak performance and efficiency. While setting up the components is an essential first step, fine-tuning each one will help you create a solution that works even better and scales seamlessly. In this section, we’ll share some practical tips for optimizing all these components, giving you the edge to build smarter, faster, and more responsive RAG applications.
LangChain optimization tips
To optimize LangChain, focus on minimizing redundant operations in your workflow by structuring your chains and agents efficiently. Use caching to avoid repeated computations, speeding up your system, and experiment with modular design to ensure that components like models or databases can be easily swapped out. This will provide both flexibility and efficiency, allowing you to quickly scale your system without unnecessary delays or complications.
Zilliz Cloud optimization tips
Optimizing Zilliz Cloud for a RAG system involves efficient index selection, query tuning, and resource management. Use Hierarchical Navigable Small World (HNSW) indexing for high-speed, approximate nearest neighbor search while balancing recall and efficiency. Fine-tune ef_construction and M parameters based on your dataset size and query workload to optimize search accuracy and latency. Enable dynamic scaling to handle fluctuating workloads efficiently, ensuring smooth performance under varying query loads. Implement data partitioning to improve retrieval speed by grouping related data, reducing unnecessary comparisons. Regularly update and optimize embeddings to keep results relevant, particularly when dealing with evolving datasets. Use hybrid search techniques, such as combining vector and keyword search, to improve response quality. Monitor system metrics in Zilliz Cloud’s dashboard and adjust configurations accordingly to maintain low-latency, high-throughput performance.
Cohere Command R optimization tips
Cohere Command R is designed for retrieval-augmented generation, making efficient context retrieval and ranking critical for system performance. Optimize retrieval pipelines by using Cohere’s embedding-based search to identify and rank the most relevant documents, reducing unnecessary input context while maintaining accuracy. Improve response quality by fine-tuning temperature settings; lower values (0.1–0.2) work best for structured, fact-based queries, while higher values introduce more variability in generated responses. Utilize prompt templates to maintain consistent formatting, ensuring clarity in output. Implement batch processing where multiple queries need similar context, reducing redundant API calls. To enhance efficiency, cache top query results and leverage incremental context updates instead of repeatedly sending full document sets. If deploying at scale, monitor latency and response consistency with real-time metrics, adjusting retrieval thresholds dynamically for optimal balance between speed and completeness.
Nomic Embed Text V2 optimization tips
Nomic Embed Text V2 is a versatile embedding model suited for general-purpose text search tasks in RAG systems. Optimize efficiency by preprocessing input data to remove irrelevant noise and focus on the most meaningful content, which can help reduce computational overhead. For faster retrieval, employ approximate nearest neighbor (ANN) search algorithms like HNSW or FAISS to speed up the search process while maintaining accuracy. Consider implementing vector quantization techniques to reduce storage space without significantly affecting retrieval quality. Utilize batching to process multiple texts in parallel and minimize API latency. If working with large datasets, regularly update embeddings to reflect the most recent information, ensuring that your retrieval system remains relevant and effective.
By implementing these tips across your components, you'll be able to enhance the performance and functionality of your RAG system, ensuring it’s optimized for both speed and accuracy. Keep testing, iterating, and refining your setup to stay ahead in the ever-evolving world of AI development.
RAG Cost Calculator: A Free Tool to Calculate Your Cost in Seconds
Estimating the cost of a Retrieval-Augmented Generation (RAG) pipeline involves analyzing expenses across vector storage, compute resources, and API usage. Key cost drivers include vector database queries, embedding generation, and LLM inference.
RAG Cost Calculator is a free tool that quickly estimates the cost of building a RAG pipeline, including chunking, embedding, vector storage/search, and LLM generation. It also helps you identify cost-saving opportunities and achieve up to 10x cost reduction on vector databases with the serverless option.
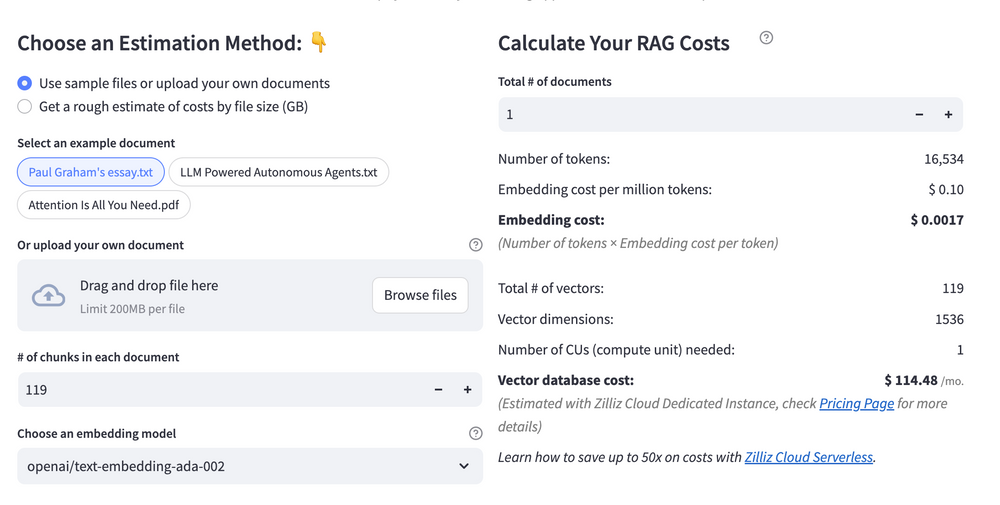 Calculate your RAG cost
What Have You Learned?
Congratulations on reaching the end of this exciting tutorial! What an incredible journey you’ve embarked on in building a cutting-edge Retrieval-Augmented Generation (RAG) system! We’ve beautifully integrated some powerful components along the way: the LangChain framework, Zilliz Cloud’s vector database, Cohere’s Command R LLM, and Nomic Embed Text V2 embedding model. Each of these plays a critical role—the LangChain framework seamlessly ties everything together, allowing for smooth interaction and workflows. The vector database from Zilliz Cloud empowers your RAG system with lightning-fast searches, enabling you to retrieve relevant data in a fraction of a second. Meanwhile, the Command R LLM brings conversational intelligence to life, transforming your user interactions into engaging and coherent dialogues. Finally, the Nomic Embed Text V2 embedding model generates rich semantic representations that add depth and context to your data, elevating your application to new heights.
And let’s not forget some of those handy optimization tips we discussed, along with the free cost calculator that will help you manage resources effectively. Now that you have all these tools at your fingertips, the world of possibilities is vast! So why wait? Start building, optimizing, and innovating your own RAG applications today! You have the power to create something amazing! Dive in and let your creativity flourish!
Further Resources
🌟 In addition to this RAG tutorial, unleash your full potential with these incredible resources to level up your RAG skills.
- How to Build a Multimodal RAG | Documentation
- How to Enhance the Performance of Your RAG Pipeline
- Graph RAG with Milvus | Documentation
- How to Evaluate RAG Applications - Zilliz Learn
- Generative AI Resource Hub | Zilliz
We'd Love to Hear What You Think!
We’d love to hear your thoughts! 🌟 Leave your questions or comments below or join our vibrant Milvus Discord community to share your experiences, ask questions, or connect with thousands of AI enthusiasts. Your journey matters to us!
If you like this tutorial, show your support by giving our Milvus GitHub repo a star ⭐—it means the world to us and inspires us to keep creating! 💖
Content
- Introduction to RAG
- Key Components We'll Use for This RAG Chatbot
- Step 1: Install and Set Up LangChain
- Step 2: Install and Set Up Cohere Command R
- Step 3: Install and Set Up Nomic Embed Text V2
- Step 4: Install and Set Up Zilliz Cloud
- Step 5: Build a RAG Chatbot
- Optimization Tips
- RAG Cost Calculator: A Free Tool to Calculate Your Cost in Seconds
- What Have You Learned?
- Further Resources
- We'd Love to Hear What You Think!
Vector Database at Scale
Zilliz Cloud is a fully-managed vector database built for scale, perfect for your RAG apps.
Try Zilliz Cloud for Free